ContentsStart0%
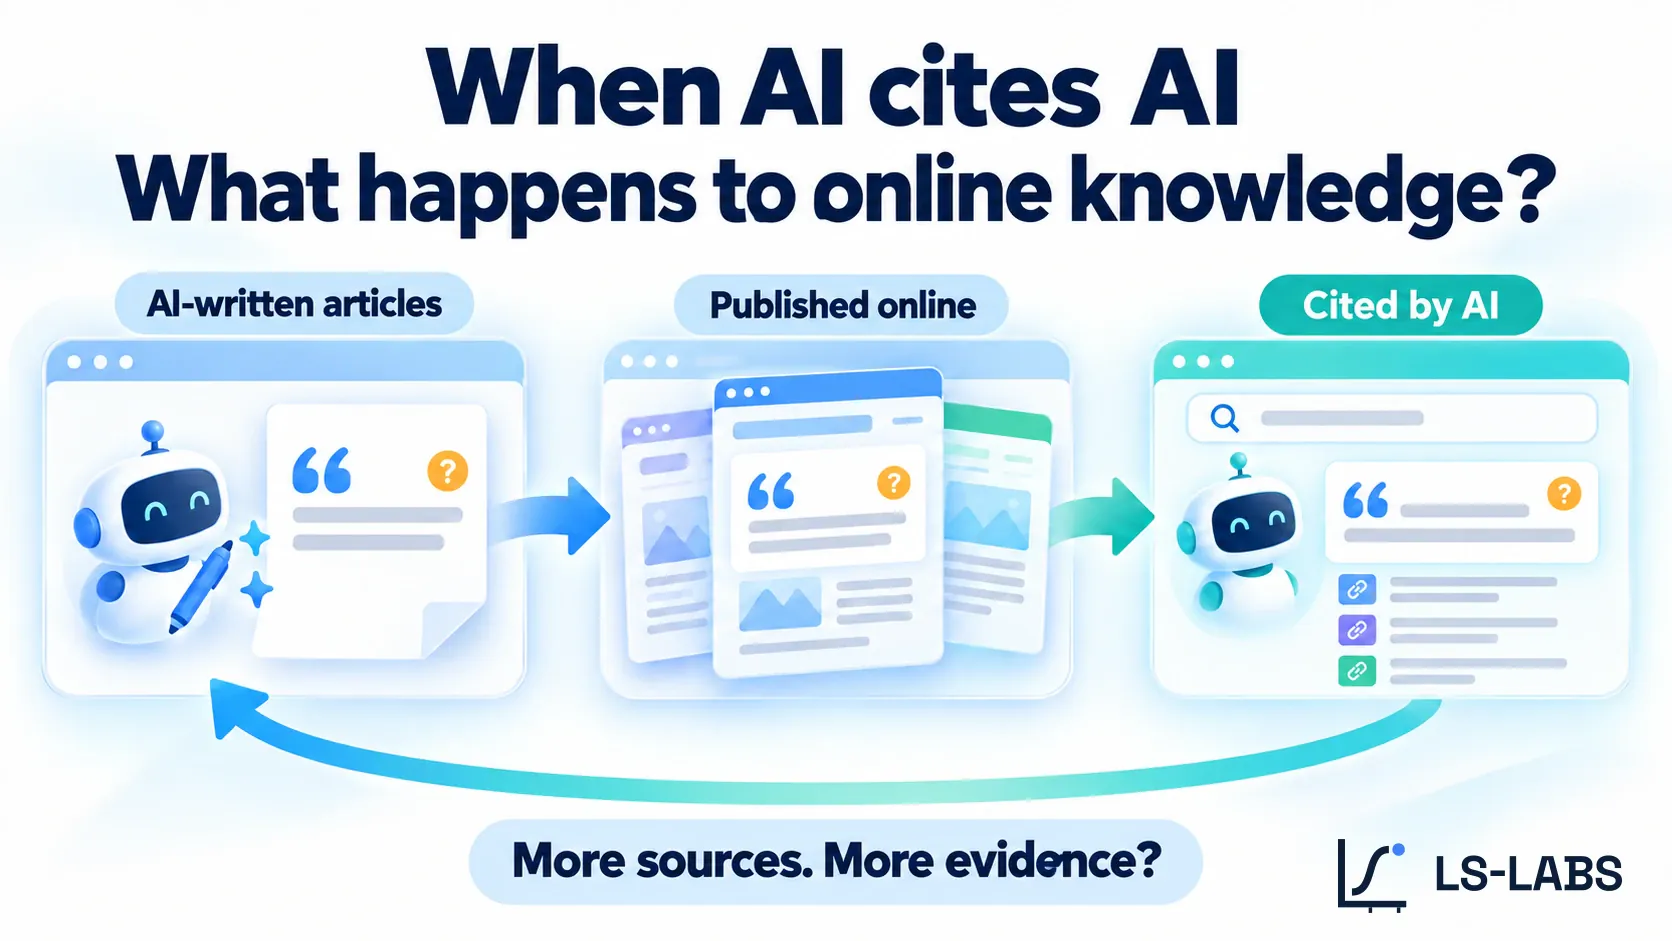
Several articles can repeat the same unsupported claim without adding independent evidence. When AI-generated writing becomes material that another AI search system retrieves, the existence of multiple links becomes an especially weak substitute for tracing the claim.
This review was first published by LS-Labs on 24 October 2026. Its central paper is Synthetic Sources?: Auditing Generative Search Engine Citations for Evidence of AI-Generated Sources, by Mowafak Allaham and Nicholas Diakopoulos at Northwestern University, arXiv v1 dated 22 May 2026. The audit belongs to those authors. It is not an LS-Labs dataset, a new experiment, or a direct measurement of long-term knowledge degradation.
How a conditional result becomes an apparently universal fact
Consider an illustrative claim that adding an FAQ increases AI citations by 40%. An author writes it without an adequate experiment; an assistant retrieves the article; another writer accepts the answer and publishes a paraphrase. More sites repeat it. A later search finds several pages carrying the same number, even though all depend on the first unsupported interpretation.
The mechanism can continue when those answers are published as further articles. The number of pages rises while the number of independent observations does not. This example describes a possible propagation route; it is not a tracked causal experiment demonstrating a particular chain of websites.
The “40%” wording also has a real research context that is often lost. Aggarwal and colleagues’ 2024 GEO paper reports up-to-40% visibility gains under its experimental setup using a 10,000-question benchmark and interventions such as quotations, statistics and source citations. The reported live Perplexity maximum was about 37%. It did not test adding an FAQ block as the intervention. A maximum under specified conditions is not a general FAQ effect.
A different study, Ahrefs’ 11 May 2026 schema analysis, followed 1,885 pages adding JSON-LD against 4,000 control pages and found little citation improvement. The pages were already frequently cited before the intervention. That does not answer whether schema helps an uncited page, nor does it establish that schema has no other search function.
| Stage | What happens | What has not been added |
|---|---|---|
| Initial assertion | A limited finding is generalised beyond its intervention and sample | A test of the new general claim |
| AI-assisted reuse | A writer accepts a generated summary without checking the paper | An independent verification |
| Multiple publications | Paraphrases appear on different websites | Independent underlying observations |
| Retrieval again | The repeated claim returns in a later answer | A reason to treat repetition as truth |
The practical distinction is between a fact, an interpretation and a source count. Even if every later writer acts in good faith, the original limitation can disappear through successive summaries.
What the Synthetic Sources? audit actually measured
Allaham and Diakopoulos curated 712 English-language, US-related questions about politics, health and the environment from Search Arena and Climate Q&A. Automated browser interaction submitted the questions to the consumer web interfaces of ChatGPT, Copilot, Gemini and Perplexity. This is an interface audit, not an interchangeable API benchmark.
| Stage | Count | Meaning |
|---|---|---|
| Questions | 712 | Selected English questions across three public-interest topics |
| Answers | 2,848 | The questions submitted across four generative search engines |
| Unique cited URLs | 26,266 | Distinct source URLs collected across the systems |
| Successfully extracted source pages | 19,154 | 72.9% of the unique cited URLs; the text-analysis denominator |
| Sources in combined likely-AI categories | 3,056 | 2,916 highly likely plus 140 likely classifications, about 16% of extracted pages |
The paper used Pangram to classify extracted source text. Its headline result therefore means that roughly one in six successfully extracted source pages was classified into the selected AI-likelihood categories. It does not mean one in six answers was false, one in six citations across the entire web was generated by AI, or that the authors verified who wrote every page.
| Classification | Pages | Treatment in the headline estimate |
|---|---|---|
| Unlikely AI | 15,815 | Not included |
| Possibly AI | 283 | Excluded as ambiguous |
| Likely AI | 140 | Included |
| Highly likely AI | 2,916 | Included |
The authors chose a conservative classification approach and described the result as a lower-bound estimate. That reasoning depends on their detector evaluation and exclusions; it does not turn model predictions into ground-truth authorship. Content inaccessible to the scraper, non-text formats and removed pages were outside this text-classification analysis. A different detector or source sample could produce a different estimate.
Large or official domains did not eliminate synthetic-source classifications
The reviewed paper reports detector-flagged sources on Reddit, the US National Library of Medicine’s PMC domain, earth.gov and Times of India, among others. The audit reports within-domain proportions of roughly 12%, 4%, 14% and close to half respectively. These describe cited and extracted pages in that audit, not all content published by each organisation.
The authors explicitly do not establish whether flagged material on official domains is high or low quality. AI-assisted production, unsupported content and factual error are related concerns but different variables. A familiar domain does not prove human authorship; a detector flag does not prove an inaccurate claim.
Provider differences concern selection, not a proven trust ranking
In the reviewed sample, ChatGPT cited about 15 sources per answer and had the lowest reported synthetic-source proportion, about 7%. Copilot cited about eight sources on average and its proportion approached three in ten. The same question set and web environment can therefore yield different observed source mixes.
That difference is consistent with platform-specific retrieval and selection, but the audit does not reveal all the internal rules responsible. It does not justify treating one historical proportion as a permanent quality score for a platform. The sources, models, interfaces and questions can change.
An answer without citations leaves a different evidence gap
About 8.8% of the 2,848 answers had no citations. The paper reported uncited responses for about 11.6% of health questions, 8.2% of environment questions and 5.7% of politics questions. The authors discuss possible reliance on internal model knowledge. Citation absence alone does not reveal every internal operation or prove that an answer is false, but it limits what the reader can verify from that answer.
Growing AI-written content changes the source environment
The audit’s first contribution is evidence that detector-identified synthetic text already enters search citation pools. It does not show an entire closed loop in which one false generated claim is repeatedly republished and later causes a particular model error. That larger mechanism remains a risk and a research question.
Pew’s August 2026 Common Crawl analysis examined about 490,000 English pages. In its .com sample, material showing substantial AI-writing or editing signals rose from 3.8% in early 2024 to 5.5% in early 2025 and 9.4% in early 2026. These estimates concern a particular sampled corpus and classification, not a census of all internet writing.
The .com estimate rose roughly 2.5-fold across the two years, with the larger increase in the most recent year. The important implication is a changing information environment, not proof that every added AI-written page is poor. Editorial oversight, sourcing and accuracy still need assessment.
Search adds evidence, but also two places to fail
A large language model (LLM)’s ability to produce coherent text is different from its ability to establish facts. Token prediction can capture complex patterns and support useful reasoning, yet fluent output alone does not show that a claim has been checked. Tool use, retrieval, calculators and other systems can change how an answer is produced; not every question follows one identical workflow.
A wiring analogy illustrates the difficulty. A conventional program may offer explicit paths that help trace an error; a language-model answer emerges from a much less readily interpretable collection of learned relationships and system choices. The analogy explains limited observability, rather than a literal model architecture or a claim that conventional software is always transparent.
Search-augmented answering resembles an open-book exercise: the model can consult external information instead of relying entirely on learned knowledge. Two requirements remain. The material must support a correct answer, and the system must find and interpret it correctly.
| Failure point | Illustration | Verification question |
|---|---|---|
| Source quality | A retrieved page repeats an unsupported statistic | Does the original evidence actually establish the claim? |
| Retrieval and interpretation | A useful source is omitted or its conditional result becomes universal | Does the final statement follow from the cited passage and its scope? |
The same question can retrieve different pages across runs, and a correct source can still be misread. Both failure points can result in equally confident prose. Unsupported or fabricated claims in a generated answer are often described as AI hallucinations; retrieval does not remove the need to check them. That is why the presence of a citation cannot replace inspecting what it supports.
The Guardian’s January 2026 reporting provided concrete examples of disputed health information in Google AI Overviews. A follow-up reported removal of summaries for some liver-test queries. These are dated reports of product behaviour, not medical instructions here, and removal does not establish every allegation or prove a general admission by Google. They illustrate why claim-level checking is especially important when the consequences of error are serious.
For SEO and GEO work, this also constrains guarantees. Publishing useful content and observing repeated answers can support a bounded account of visibility. It cannot establish that a brand will always be selected or that every future answer will remain accurate.
When people trust the answer without opening the sources
The risk is not limited to what a model retrieves. The answer also changes how people encounter information. A concise generated explanation can make source inspection feel unnecessary, especially when the reader lacks the background needed to notice a gap.
Cinelli and colleagues’ 2021 echo-chamber research describes reinforcement of views within restricted information environments. Jacob, Kerrigan and Bastos’ 2025 “chat-chamber” study examined a related human–AI interaction. Participants used ChatGPT 3.5 or Google to investigate the numbers of LGBTQIA+ elected representatives in India and Ireland, followed by semi-structured interviews.
The study describes participants accepting incorrect but apparently plausible information and incorporating it into their understanding without sufficient cross-checking. It does not measure every contemporary chatbot or every user. Its relevance is a mechanism of uncritical acceptance, not a universal claim that users never verify.
Sharma, Liao and Xiao’s CHI 2024 experiment examined information diversity. Compared with traditional search, conversational-AI participants asked more questions aligned with their pre-existing positions; an assistant deliberately made to agree with the user amplified that pattern. This provides a separate behavioural perspective, rather than a replication of the synthetic-source audit.
Five pages can still be one piece of evidence
Cross-checking works when sources have independent access to evidence. If five articles merely paraphrase one original assertion, the five URLs do not supply five independent observations. Tavlin’s explanation of circular reporting describes this problem without requiring AI; generated writing can make repetition cheaper and provenance less obvious.
Pew’s 900-adult browsing study found source-link clicks in 1% of visits to Google pages containing an AI summary. Traditional-result clicks occurred in 8% of those visits versus 15% without a summary. These are observed visits in that study, not proof that all users abandoned checking or that AI caused every difference.
Yet citation marks can still influence trust. In Ding and colleagues’ 2025 experiment with 303 participants, chatbot answers were presented with citations differing in number and relevance. Citation presence increased trust even when the linked material was randomly selected or irrelevant. Fewer than one in ten cited answers received a source click; participants who actively inspected sources gave lower trust ratings.
The experiment does not show that all citations are useless. It shows why citation appearance and evidential support must be evaluated separately. A reader can use a footnote as a confidence signal without performing the verification that would justify that confidence.
| Situation | Independent evidence added? | What to do |
|---|---|---|
| Several sites repeat one statistic | Not established | Follow their references back to the original study |
| A cited paper tests a different intervention | No evidence for the new intervention | Retain the actual treatment and population |
| A source genuinely replicates a result | Potentially, under its own conditions | Compare methods, periods and limitations |
| A detector labels a page synthetic | Evidence about a classification | Check factual support separately |
Fast answers and understanding are different outcomes
On the supply side, AI can reduce the effort required to draft, summarise and repackage material. On the demand side, it can provide a polished answer quickly. Neither speed proves that readers have acquired the ability to check the answer or apply it correctly.
The same concern surfaces in 2026 reporting on AI-generated mathematics. An NPR report discusses a claimed result related to Navier–Stokes and the difficulty of learning from its proof; Fortune’s October reporting discusses the release of solutions to more than 370 mathematical challenges and disagreements among mathematicians. These news examples raise a question about inspectable reasoning. They are not independent mathematical validation by LS-Labs, nor evidence that the synthetic-source audit measured this effect.
The author’s concern is that obtaining an answer can be mistaken for acquiring understanding. A useful knowledge process also explains why a conclusion follows, how to test it and when its conditions no longer hold. The issue is verification and learning, not whether every use of AI in writing is unacceptable.
Trace the claim before counting its repetitions
The possible chain is straightforward: AI-assisted writing is published, indexed and retrieved; a new answer uses it; another writer republishes that answer. None of the individual participants needs to intend deception for an unsupported claim to acquire the appearance of consensus.
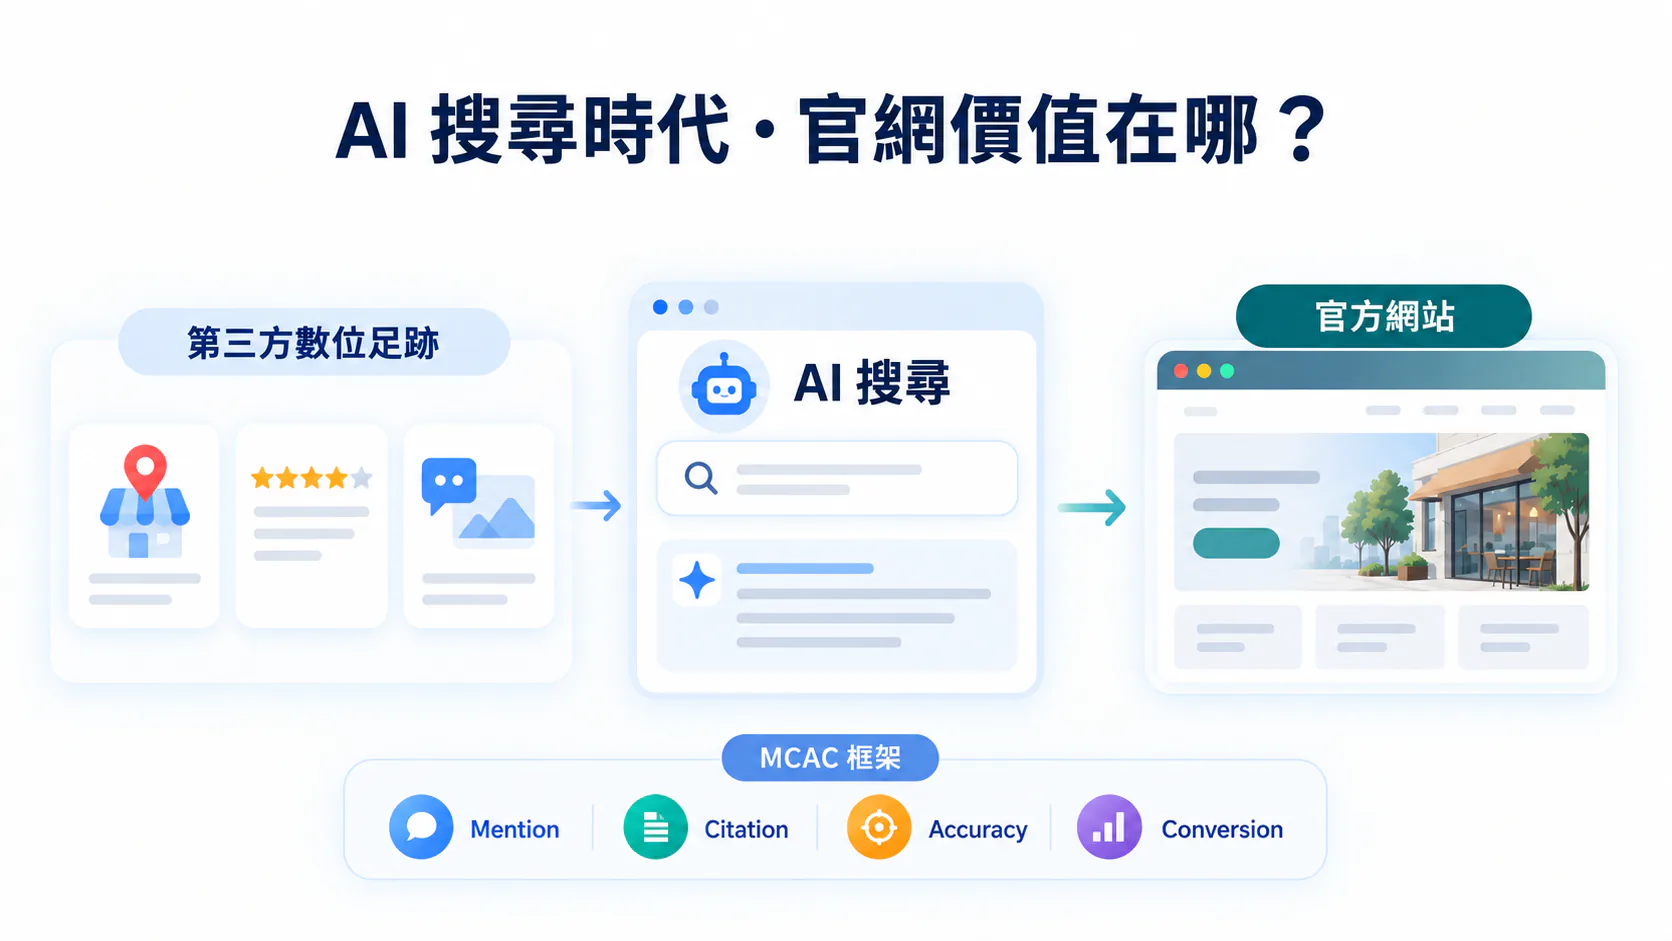
When reviewing a brand’s presence in AI answers, record citation and factual accuracy separately. The GEO guide illustrates that distinction through the four MCAC checks.
A deliberately extreme thought experiment makes the distinction clear: if many websites repeated an incorrect arithmetic statement, the repeated text would not change the arithmetic. The practical response is not a prediction of inevitable knowledge collapse, but preserving ways to compare a claim with evidence outside its own repetition.
For an AI-search researcher and content creator, this risk is personal rather than abstract. Using AI to increase publishing output may improve efficiency while also adding another unexamined version of an existing claim. The central paper does not predict what the entire web will become, and it does not establish that all generated writing reduces information quality.
What it does support is a reason to question provenance. A source can itself have been generated; multiple pages can share one origin; a citation can reassure without supporting the statement. Inspect the original intervention, sample, denominator and passage before turning an attractive number into advice.
When designing an audit, separate detection of synthetic text, factual accuracy, independence of sources and effects on users. The AI visibility measurement guide discusses how to keep such claims bounded; it does not convert this review into a new experiment.
References and research boundaries
Reviewed paper, datasets and detector
- Allaham and Diakopoulos (2026), Synthetic Sources?, v1, 22 May. The source paper and its figures are CC BY 4.0; the tables above restate its reported results with attribution.
- De La Calzada et al. (2024), ClimateQ&A.
- Emi and Spero (2024), Pangram classifier technical report.
- Miroyan et al. (2025), Search Arena.
Related research
- Aggarwal et al. (2024), GEO: Generative Engine Optimization.
- Cinelli et al. (2021), The echo chamber effect on social media.
- Ding et al. (2025), Citations and Trust in LLM Generated Responses.
- Jacob et al. (2025), The chat-chamber effect.
- Sharma et al. (2024), Generative Echo Chamber?.
Context sources
- Pew, AI-written internet content, 20 August 2026; Pew, AI-summary clicks, 22 July 2025.
- Linehan and Guan, schema and AI citations, 11 May 2026.
- Gregory, Guardian investigation, 2 January 2026; follow-up, 11 January.
- NPR mathematics report, 22 September 2026; Kahn, Fortune report, 7 October.
- Tavlin, How false news can spread, TED-Ed, 2015.
This is a paper review and author interpretation. Detection estimates, behavioural experiments and media examples retain their separate methods. No new model calls, detector runs or longitudinal feedback-loop experiment are claimed.